Gemini 3.8 Live API: Pricing, Extended Thinking and Setup
Gemini 3.8 Live and Live Extended Thinking: native speech-to-speech, $0.005/min in, $0.018/min out, 128K context. On RouterPlex in a few days.
Google shipped Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking on 15 September 2026. They are native speech-to-speech models for the Live API: you talk, they talk, tools can run in the background, and the conversation does not have to go silent while a function returns.
The model IDs are gemini-3.8-live and gemini-3.8-live-extended-thinking. Paid audio is $0.005 per minute in and $0.018 per minute out. Context is 128K in and 64K out. They are not Gemini 3.8 Flash. Flash is chat. These are live voice.
They are not on RouterPlex yet. Both IDs land on this catalog in a few days, at Google list rates, 0% markup, on the same prepaid key as the rest of the lineup. Until then, Flash is the live Google route.
Sources: Google's product announcement (15 September 2026, Tom Ouyang and Malini Jaganathan), the developer post (Alisa Fortin and Thor Schaeff), the Gemini 3.8 Live and Live Extended Thinking model pages, Live API thinking, Gemini API pricing, and the Gemini 3.8 Audio model card, checked 15 September 2026.
Two models, two jobs #
Google's own thinking guide is the useful split. Do not pick Extended Thinking because the name sounds smarter.
gemini-3.8-live | gemini-3.8-live-extended-thinking | |
|---|---|---|
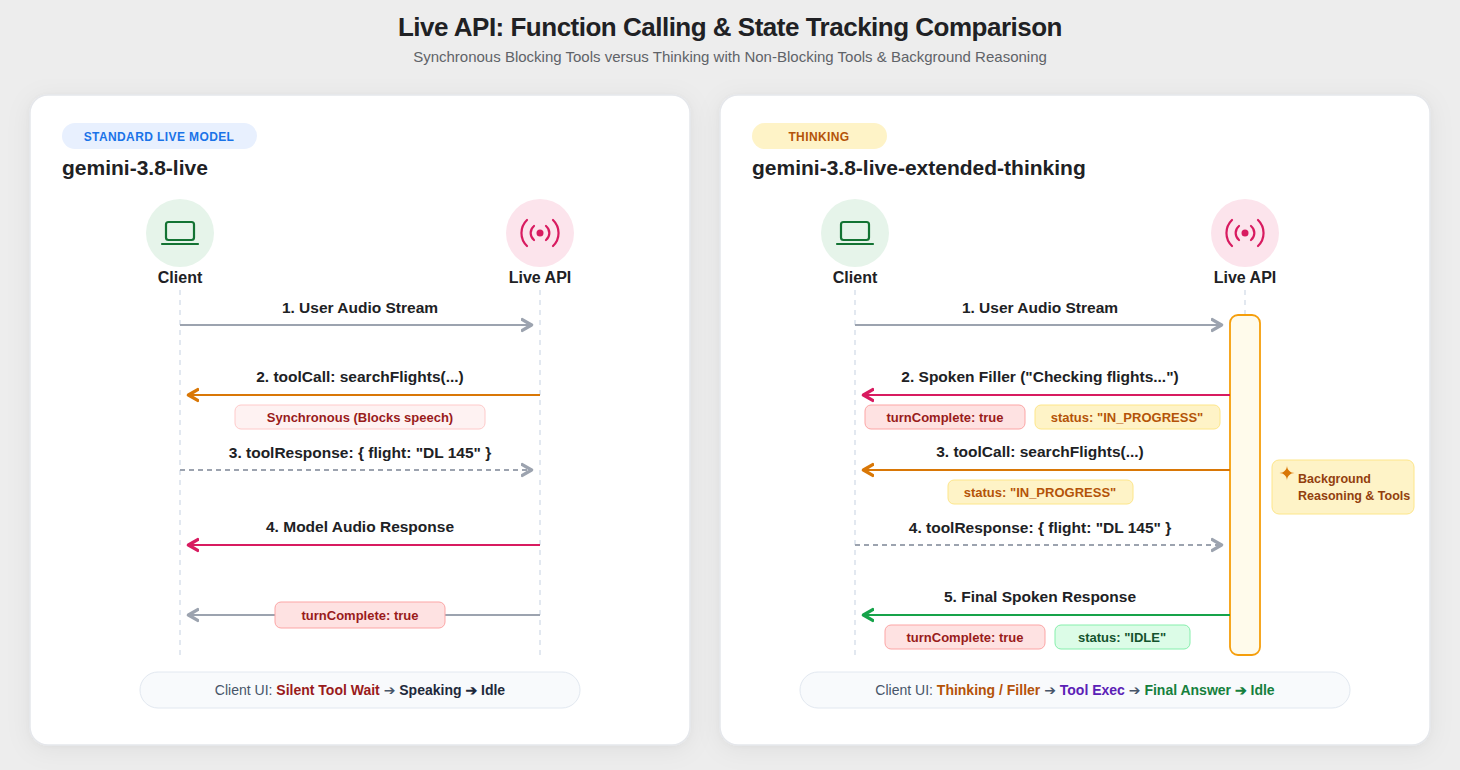
| Job | Low-latency voice. Direct tasks. Fast tools. | Multi-step work. Slow tools. Planning while speaking. |
| Reasoning | Interleaved. Fixed latency. thinking_level is not supported. | Background reasoning. thinking_level: low, medium, or high. MINIMAL is not supported. |
| Tools | Blocking and non-blocking. Async is the default. | Non-blocking only. Synchronous tools return a hard error. |
| When a spoken turn ends | turnComplete: true means idle. | turnComplete: true means that utterance finished. Read interaction_status: IN_PROGRESS or IDLE. |
| Dead air | The model waits for the tool. | The model keeps talking: "Let me check that…" then narrates progress. |
| Examples Google names | Triage, language practice, voice search, sensors, device control. | Diagnostics across logs, travel booking across APIs, STEM/code tutoring, any tool that takes seconds. |
Both take text, images, audio, and video. Both return text and audio. Both support search grounding and function calling. Neither supports caching, batch, code execution, file search, structured outputs, Maps grounding, image generation, or URL context.
Proactive audio is on and cannot be turned off. Setting proactive_audio: false errors. Affective dialogue is gone: drop enable_affective_dialog if you still send it.
Gemini 3.8 Live API pricing #
Google bills both Live 3.8 IDs at the same paid rates. Output includes thinking tokens.
| Channel | Per 1M tokens | Per minute (Google's equivalent) |
|---|---|---|
| Text input | $0.75 | — |
| Audio input | $3.00 | $0.005 |
| Image / video input | $1.00 | $0.002 |
| Text output | $4.50 | — |
| Audio output | $12.00 | $0.018 |
A full duplex hour where both sides speak the whole time is 60 × $0.005 + 60 × $0.018 = $1.38. Real calls have silence, so that is a ceiling, not a typical invoice. Thinking tokens still land on the output line. A high thinking session that talks little can still cost more than a chatty gemini-3.8-live turn.
Google's per-minute audio figures match 25 audio tokens per second: 1,500 tokens/min × $3 / 1M = $0.0045, published as $0.005; 1,500 × $12 / 1M = $0.018 exactly.
Search grounding is the Gemini 3.x bucket: 5,000 free requests per month, then $14 per 1,000. A customer prompt can fire more than one search.
When these IDs land on RouterPlex, the billed rate is the live catalog row, not a screenshot in this post. No per-token markup. Prepaid balance. Hard per-key budget. The session stops at $0. It does not overdraft.
Cost of one voice hour, in numbers #
| Mix | Approx. cost |
|---|---|
| 60 min audio in + 60 min audio out | $1.38 |
| 60 min audio in + 15 min audio out | $0.57 |
| 10 min audio in + 10 min audio out | $0.23 |
Give a voice key its own budget. A forgotten open mic is a continuous input stream at $0.005/min, plus whatever the model says back, plus thinking. That is a different failure mode from a 40K chat completion.
Gemini 3.8 Live specifications #
| Capability | Gemini 3.8 Live / Live Extended Thinking |
|---|---|
| Model IDs | gemini-3.8-live, gemini-3.8-live-extended-thinking |
| Provider | |
| Family | Gemini 3.8 Audio, based on Gemini 3 Pro |
| Protocol | Live API (realtime session), not chat completions |
| Context window | 131,072 input / 65,536 output (model pages); 128K / 64K (model card) |
| Knowledge cutoff | January 2025 |
| Inputs | Text, images, audio, video |
| Outputs | Text and audio |
| Languages | 97, with mid-conversation switches |
| Search grounding | Yes |
| Function calling | Yes (async-only on Extended Thinking) |
| Thinking | Yes |
| Caching / batch | No |
| Watermark | SynthID on generated audio |
| Model page status | Stable |
Google's product post also claims alphanumeric precision (confirmation codes, claim numbers) and visual grounding: the model can use what the camera sees while you talk. Default turn coverage includes video frames. Only send frames you mean to pay for.
Benchmarks Google is citing #
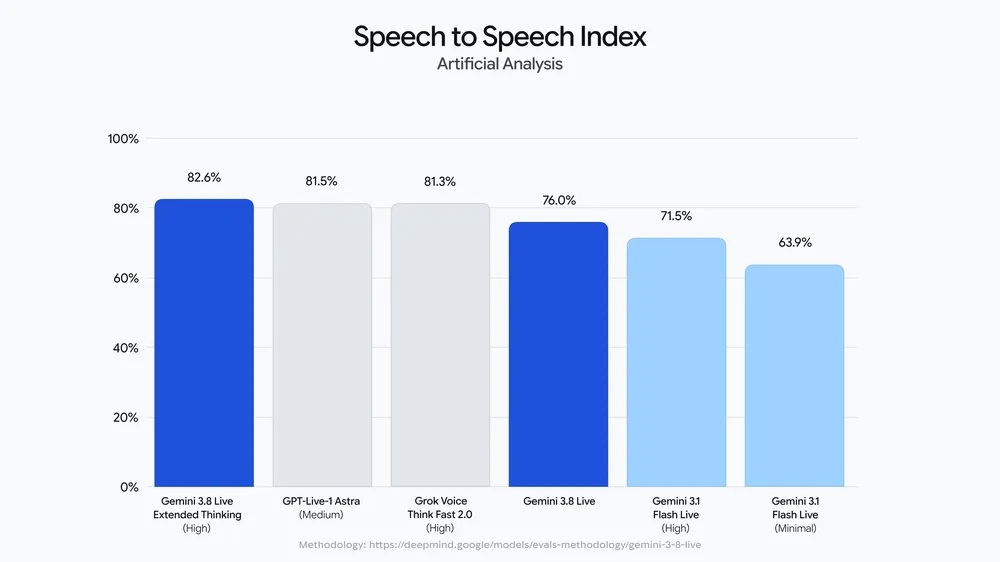
These are Google's numbers from the 15 September announcement, plus the Artificial Analysis speech-to-speech table checked the same day. They are not RouterPlex evals.
| Claim | Figure | Who |
|---|---|---|
| Speech-to-Speech Quality Index, Extended Thinking (High) | 82.6, #1 | Artificial Analysis; Google |
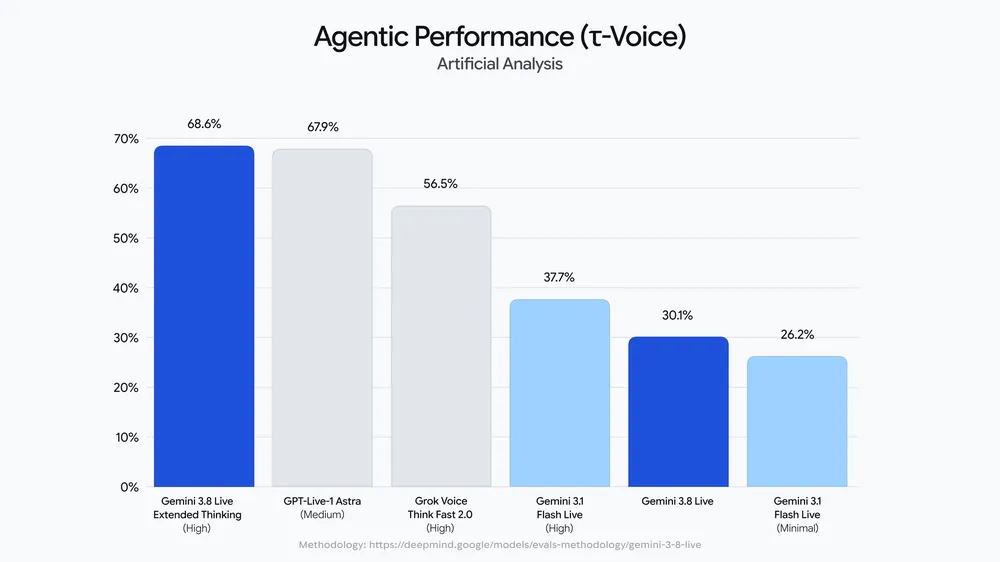
| τ-Voice (agentic task completion), Extended Thinking | 68.6% | |
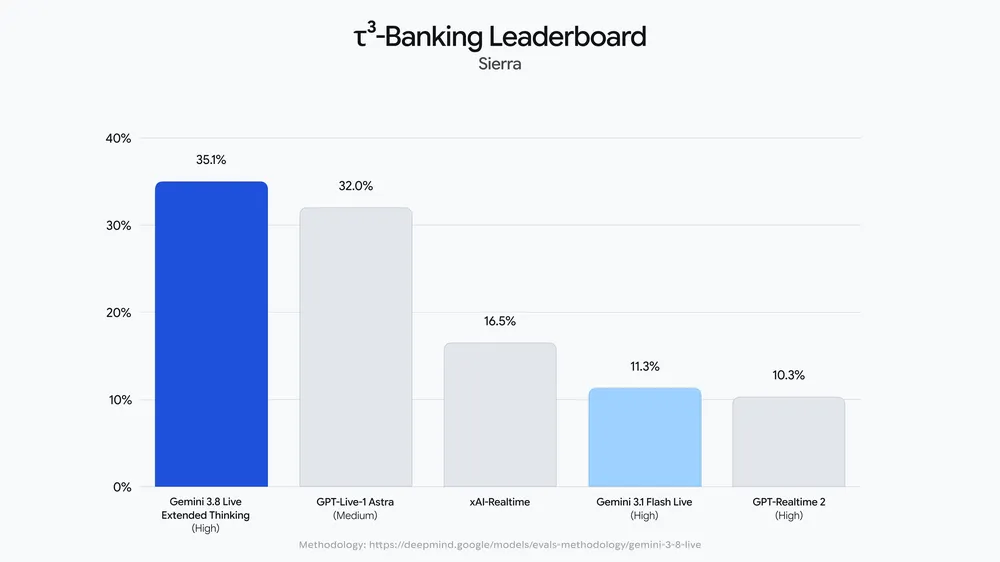
| Sierra τ-Voice-banking, Extended Thinking | 35.1% | |
| Big Bench Audio, Extended Thinking | 97.7% | Google; AA ranks that row 4th on reasoning quality |
| Gemini 3.8 Live, AA overall | 76.0 | Artificial Analysis |
| Gemini 3.8 Live, Full Duplex Bench | 96.1% | Artificial Analysis |
| Gemini 3.8 Live, Speech Agent Arena | 2nd |
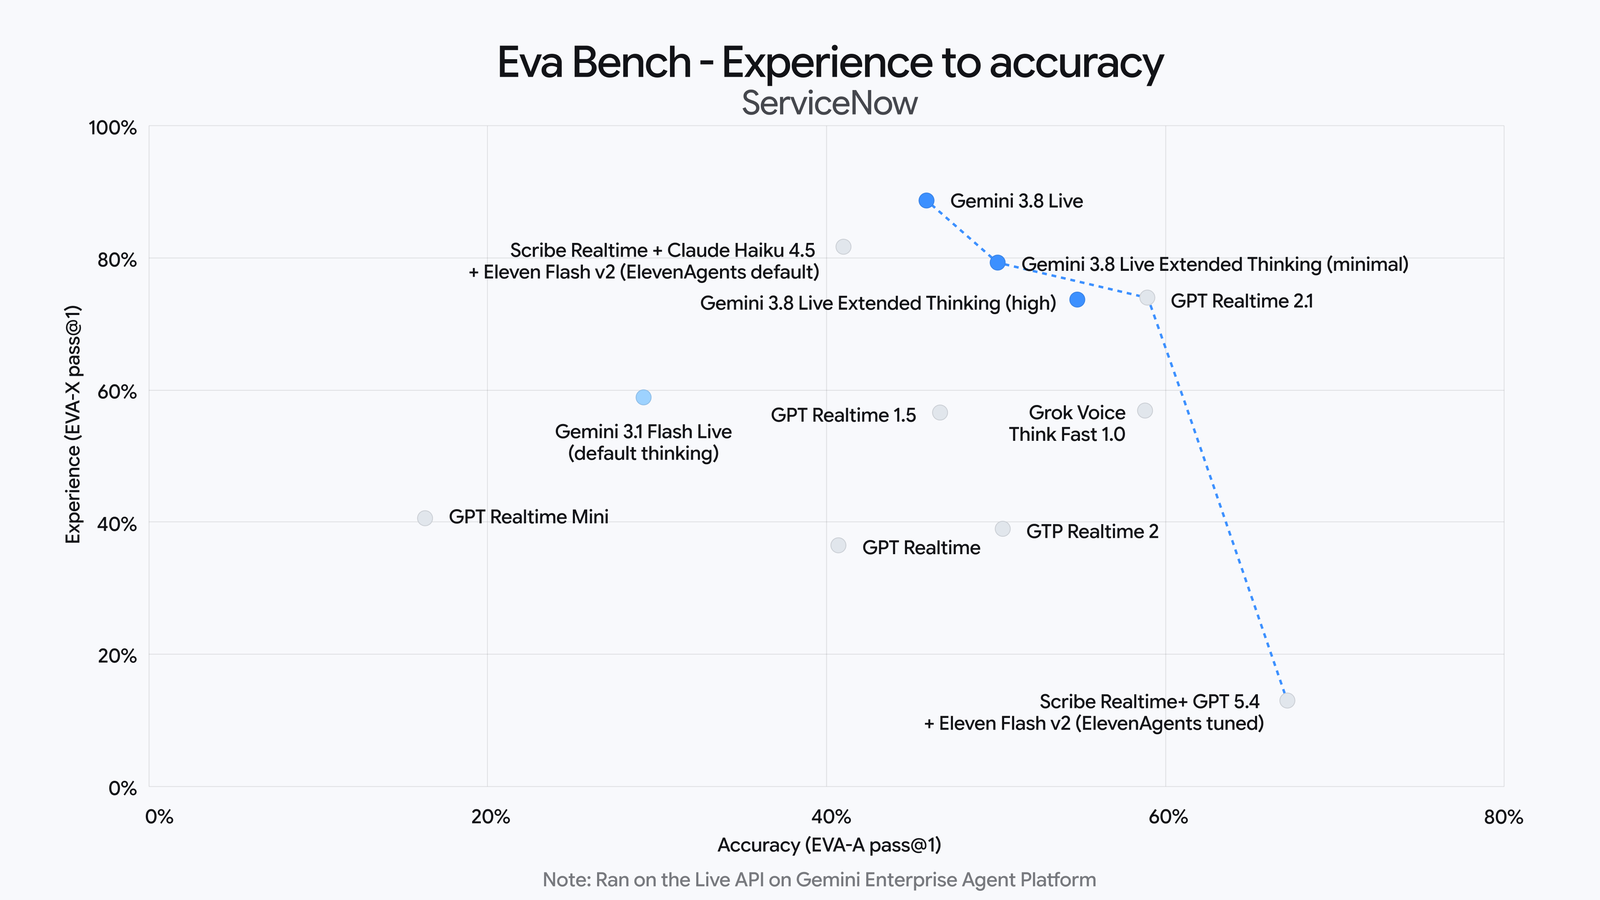
Google also says the pair sits on ServiceNow's EVA-Bench Pareto frontier for accuracy vs conversational quality, run on the Live API on Gemini Enterprise Agent Platform.
Read the table as "this is a voice agent model," not "this replaces Flash for coding." τ-Voice for plain Live is 30.1% on AA. The Extended Thinking lift is the point of the second ID.
What changed from Gemini 3.1 Flash Live #
If you are on gemini-3.1-flash-live-preview, Google's migration notes:
- Change the model string to
gemini-3.8-live. - Omit
thinking_level/thinking_configon the non-thinking ID. - Async
NON_BLOCKINGtools are the default.BLOCKINGstill works on Live, not on Extended Thinking. send_client_contentworks for the whole session.turn_complete=trueinterrupts generation.- Proactive audio is permanent.
- Response modality is audio. Turn on output transcription if you need a text log.
For Extended Thinking, the extra work is client state: keep listening after turnComplete, and treat interaction_status as the idle signal. Google's thinking doc is the protocol, not a blog gloss.
Gemini 3.8 Live vs Gemini 3.8 Flash #
| 3.8 Flash | 3.8 Live | |
|---|---|---|
| ID | gemini-3.8-flash | gemini-3.8-live |
| Surface | Chat / completions | Live API |
| Context | 1M | 128K |
| Intro chat rate | $0.75 / $3.75 per 1M through 31 Dec 2026 | Not a chat SKU |
| Audio | Image in, text out | Native audio in and out |
| On RouterPlex | Live now | In a few days |
| Cutoff | March 2026 | January 2025 |
A voice agent that needs 2026 facts should turn on search grounding, or keep a Flash/chat model on the same prepaid balance for lookup. The Live cutoff is older than Flash.
On Google's products today, on RouterPlex in a few days #
Google is rolling the models out now:
- Developers: Gemini API and Google AI Studio Live.
- 3.8 Live for everyone: Search Live.
- Extended Thinking for everyone: Gemini Live; Docs Live for Google AI Pro and Ultra; Gmail Live and Keep Live for Google AI subscribers.
- Enterprises: private preview in Gemini Enterprise.
Partners named for the Live API plumbing: Agora, Fishjam, LangChain, LiveKit, Pipecat, Vercel, Vision Agents. Sample apps: google-gemini/gemini-live-api-examples.
RouterPlex: gemini-3.8-live and gemini-3.8-live-extended-thinking are scheduled for this catalog in a few days. They will not appear as a drop-in /v1/chat/completions model. They need a realtime session. Do not paste the ID into Cursor or Claude Code and expect a voice agent.
Until the rows exist, the Google chat model already on this key is gemini-3.8-flash. Create a prepaid account, set a hard budget, and use Flash for text. When the Live IDs publish, put them on a separate key with a small cap. An open microphone plus thinking tokens is how a voice demo becomes an invoice.
Create a RouterPlex account if you want the key ready. The Gemini 3.8 Flash pricing post is the current Google chat route. This page will follow the catalog the day the Live IDs ship.
Common questions
Frequently asked questions
How much does the Gemini 3.8 Live API cost?
Google lists Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking at the same paid rates: $0.75 per 1M text input, $3.00 per 1M audio input ($0.005/min), $1.00 per 1M image/video input ($0.002/min), $4.50 per 1M text output, and $12.00 per 1M audio output ($0.018/min). Output includes thinking tokens. RouterPlex will bill Google list rates with no markup when the routes land.
What is the difference between Gemini 3.8 Live and Live Extended Thinking?
gemini-3.8-live is the low-latency default: interleaved reasoning, one spoken turn, and both blocking and non-blocking tools. gemini-3.8-live-extended-thinking is for multi-step work: configurable thinking_level (low, medium, high), asynchronous tools only, and spoken progress while tools run. On Extended Thinking, turnComplete: true does not mean the session is idle — you must read interaction_status.
What is the Gemini 3.8 Live context window?
Google's model pages list 131,072 input tokens and 65,536 output tokens. The DeepMind model card rounds that to 128K input and 64K output. Knowledge cutoff is January 2025.
Is Gemini 3.8 Live the same as Gemini 3.8 Flash?
No. Gemini 3.8 Flash is a chat/completions model with a 1M context window at an intro $0.75 / $3.75 per 1M. Gemini 3.8 Live is a native audio-to-audio Live API model for real-time voice. Different IDs, different protocol, different bill.
When will Gemini 3.8 Live be on RouterPlex?
In a few days. The IDs are gemini-3.8-live and gemini-3.8-live-extended-thinking. They are not in the catalog yet. Gemini 3.8 Flash is already live for chat.
Can I call Gemini 3.8 Live with the OpenAI SDK chat completions endpoint?
No. These are Live API models. They need a realtime session, not POST /v1/chat/completions. Pointing an OpenAI chat client at gemini-3.8-live will not start a voice session. Use Gemini 3.8 Flash on RouterPlex today if you want Google's current Flash over chat.
Run the smallest paid test.
Add $5, cap the key, and verify the result with your own workload. No subscription, and credit never expires — a first top-up of $25+ is matched with $25 extra.