Eleven v4 Turbo API Pricing: $0.011 per 1K Characters
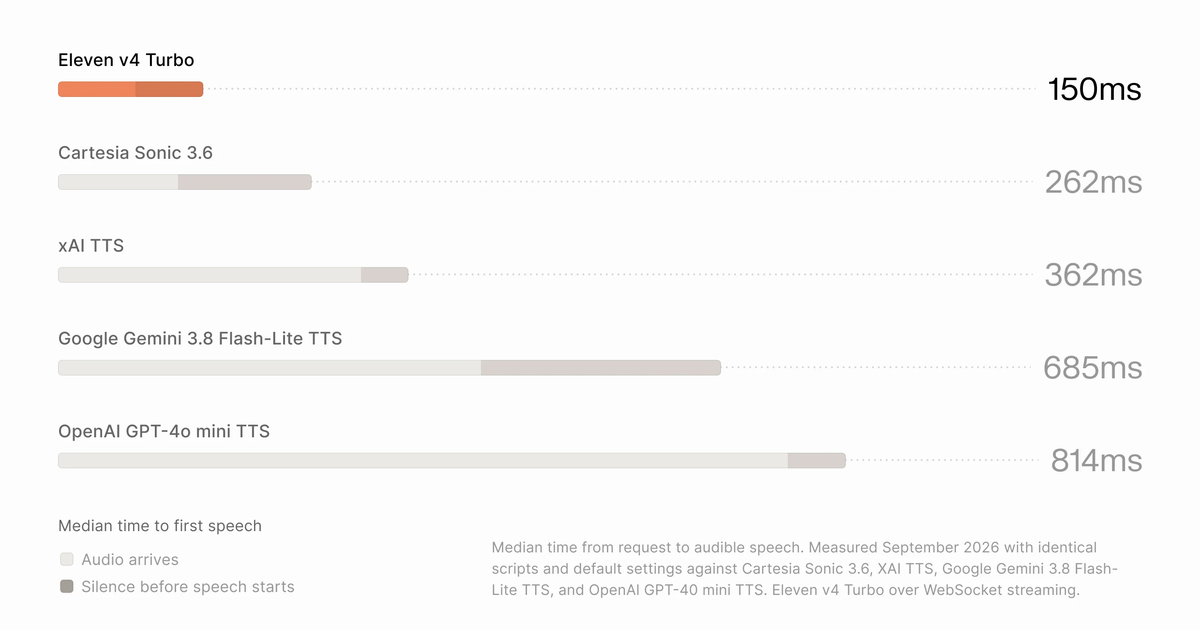
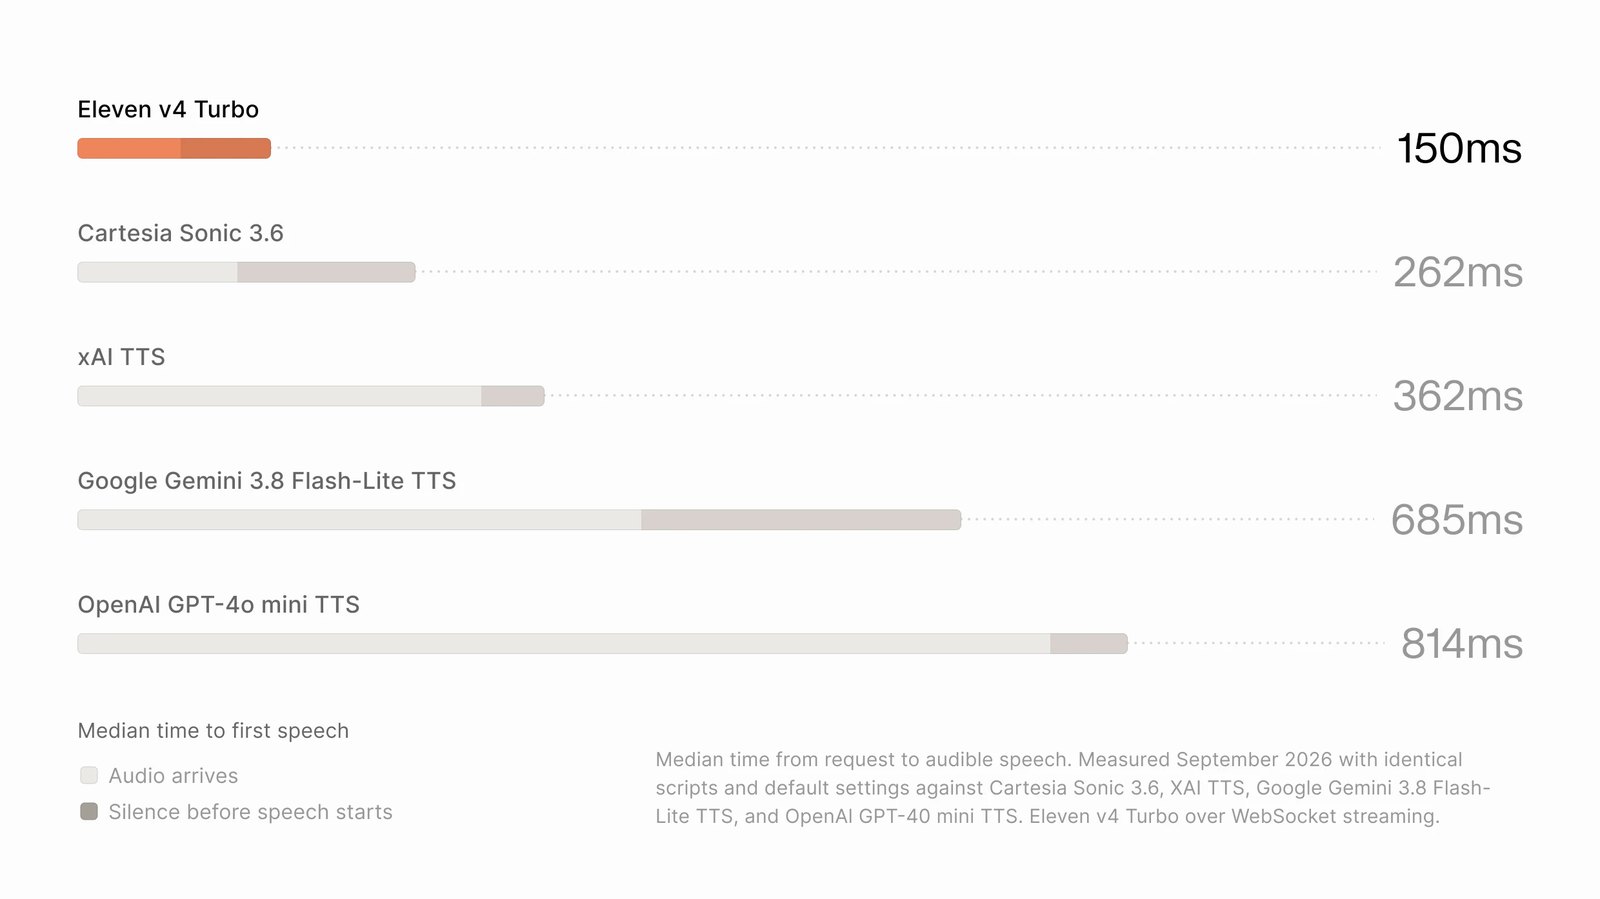
Eleven v4 Turbo is $0.011 per 1K characters, list $0.04, with a 150 ms median time to first speech on ElevenLabs' chart. Not on RouterPlex yet.
Eleven v4 Turbo is the low-latency variant of Eleven v4, both launched 28 September 2026. The model id is eleven_v4_turbo. Eleven v4 Turbo API pricing is $0.011 per 1,000 characters, struck through against a list price of $0.04 per 1,000 characters.
Eleven v4 Turbo is not on RouterPlex yet. Register to use the current 60+ models on one prepaid key. The new speech model is available here once the marketplace lists it. Today's chat routes do not return audio.
Sources: ElevenLabs' Eleven v4 announcement (28 September 2026), the models overview, and API pricing, checked 28 September 2026.
Eleven v4 Turbo API pricing #
The Turbo card uses the same 72% off until Oct 12 label as v4. The page does not print the year. $0.011 / $0.04 matches that discount. Per 1M characters the promo is $11 and the list is $40. One thousand characters is $0.011 on promo and $0.04 at list. The page also prints about $0.01 per minute at the promo rate.
| Promo per 1K | List per 1K | Promo per 1M characters | |
|---|---|---|---|
| Eleven v4 Turbo | $0.011 | $0.04 | $11 |
| Eleven v4 | $0.022 | $0.08 | $22 |
That promo is ElevenLabs' price. It is not a RouterPlex credit and it is not a rate this catalog bills.
Latency: 100 ms and 150 ms are different measurements #
The docs describe eleven_v4_turbo as median inference latency of about 100 ms. The dagger says that figure excludes application and network latency.
The launch chart is a different clock. It labels median time to first speech:
| System | Median time to first speech |
|---|---|
| Eleven v4 Turbo | 150 ms |
| Cartesia Sonic 3.6 | 262 ms |
| xAI TTS | 362 ms |
| Gemini 3.8 Flash-Lite TTS | 685 ms |
| OpenAI GPT-4o mini TTS | 814 ms |
Measured September 2026, identical scripts, default settings, Turbo over WebSocket. The chart's bars have two segments, audio arrives and silence before speech starts. The totals above are the labeled values; ElevenLabs does not print the split between the two segments.
The blog footnote also says network latency was measured and removed. Quote the chart total when you compare vendors. Quote the docs' 100 ms figure when you mean inference time with application and network excluded.
How you call it #
| Eleven v4 Turbo | |
|---|---|
| Model id | eleven_v4_turbo |
| API | Text to Dialogue websocket |
| Languages | 90+ |
| Character limit | Not printed in the v4 row of the character-limit table |
| On RouterPlex | When listed |
v4 itself is the Text to Dialogue HTTP API, with a printed cap of 10,000 characters. Turbo is the websocket path for agents that need the first audio packet quickly. ElevenLabs says both are in ElevenAgents, ElevenCreative, and ElevenAPI.
A live RouterPlex call is still text #
gemini-3.8-flash is live here at $0.75 input and $3.75 output per 1M tokens. It is the chat model, not Gemini 3.8 Flash TTS.
curl https://api.routerplex.com/v1/chat/completions \-H "Authorization: Bearer $ROUTERPLEX_API_KEY" \-H "Content-Type: application/json" \-d '{"model": "gemini-3.8-flash","messages": [{"role": "user", "content": "Write a one-sentence hold message for a voice agent."}]}'
Balance never goes negative. The hard spend limit is on the key. See the catalog and how the OpenAI-compatible API works.
On RouterPlex, once Turbo is listed #
The route name lands with the catalog row. Price will follow the vendor list price at 0% markup, prepaid, with the same hard per-key budget. Create an account for the 60+ models that are live now, and for eleven_v4_turbo when this marketplace carries it. Until that row exists, the websocket host is ElevenLabs, not api.routerplex.com.
Common questions
Frequently asked questions
How much does Eleven v4 Turbo cost?
On elevenlabs.io/pricing/api, checked 28 September 2026, Eleven v4 Turbo shows $0.011 per 1,000 characters struck through against $0.04 per 1,000 characters. The card says 72% off until Oct 12 and about $0.01 per minute at the promo rate. RouterPlex does not bill this model.
What is the Eleven v4 Turbo model ID and latency?
The id is eleven_v4_turbo. Docs list median inference latency of about 100 ms, excluding application and network latency. The launch chart labels median time to first speech at 150 ms for Turbo over WebSocket. Use the number that matches the measurement you care about.
What is the character limit for eleven_v4_turbo?
The ElevenLabs character-limit table prints 10,000 characters for eleven_v4. eleven_v4_turbo is not listed there yet. Check the models overview before you batch long scripts.
Is Eleven v4 Turbo on RouterPlex?
Not yet. Register for the current 60+ models. Turbo can be used here once it is live. Chat completions on this catalog return text, not audio.
Should I use Eleven v4 or Eleven v4 Turbo?
v4 is the quality Text to Dialogue model at $0.022 per 1K characters on promo, list $0.08. Turbo is the websocket variant at half those character rates, aimed at realtime agents. Pick from a latency budget and a listening test, not from the sticker alone.
Run the smallest paid test.
Add $5, cap the key, and verify the result with your own workload. No subscription, and credit never expires — a first top-up of $25+ is matched with $25 extra.