Qwen4-Max Preview API: $2/$6 Pricing, Setup and Empty-Reply Fix
Qwen4-Max Preview API pricing: $2 input, $6 output per 1M tokens on RouterPlex, 1M context. Alibaba retires the preview 25 Nov 2026. Setup and fixes.
Model releases·Published ·By RouterPlex·6 min
qwen4-max-preview is live on RouterPlex at vendor list price, 0% markup, $0 top-up fee.
On this page
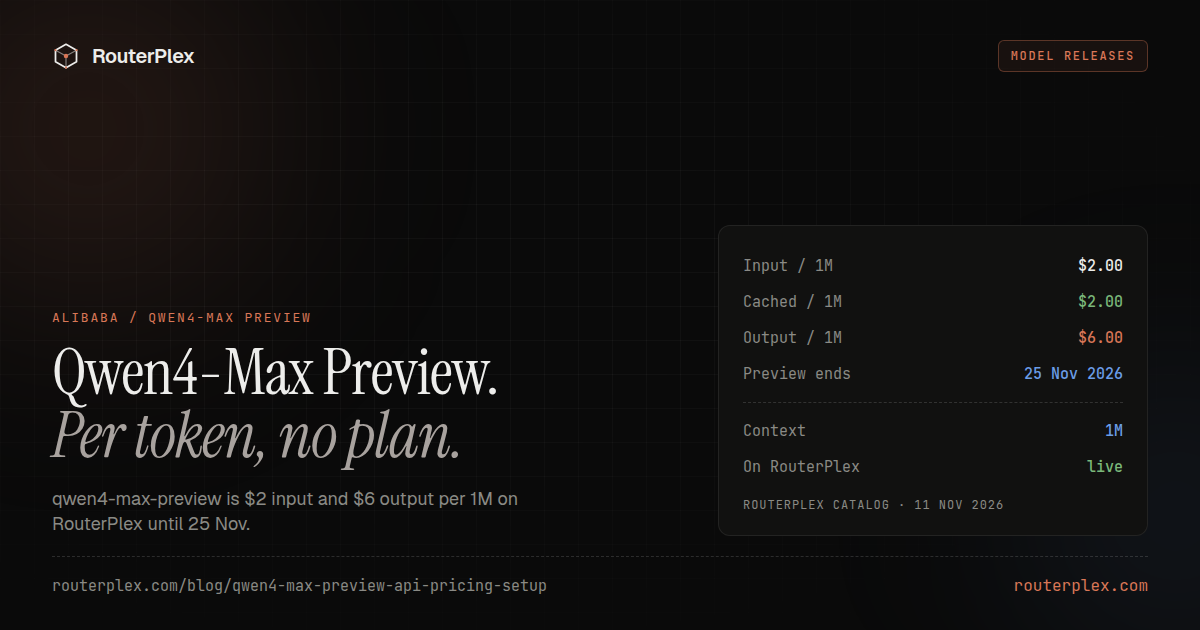
Qwen4-Max Preview API pricing on RouterPlex is $2 per 1M input tokens and $6 per 1M output tokens, with a 1M-token context window. The model ID is qwen4-max-preview. Alibaba released it on 11 November 2026 and sells it only inside its Token Plan subscription, with no per-token price of its own. Alibaba plans to retire the preview at 16:00 UTC on 25 November 2026.
That gives you two weeks to test Alibaba's first Qwen4 model. On RouterPlex you pay per token from a prepaid balance, through the OpenAI or Anthropic API format, with no subscription.
Checked 11 November 2026: Neurohive's Qwen4-Max launch notes, OrcaRouter's Token Plan breakdown, the AIHubMix empty-reply write-up, and the live RouterPlex catalog. Alibaba has published no benchmark scores for this model yet. Rates change, so check the Qwen4-Max Preview price page before you lock a budget.
Qwen4-Max Preview API pricing
USD per 1M tokens, as billed on RouterPlex on 11 November 2026.
| Line | RouterPlex qwen4-max-preview | Alibaba direct |
|---|---|---|
| Input | $2.00 | No per-token price |
| Output | $6.00 | No per-token price |
| Cached input (read) | $2.00 | No per-token price |
| Context window | 1M tokens | 1M tokens |
| How you pay | Prepaid balance, per token | Token Plan credits, $6 to $43 a month |
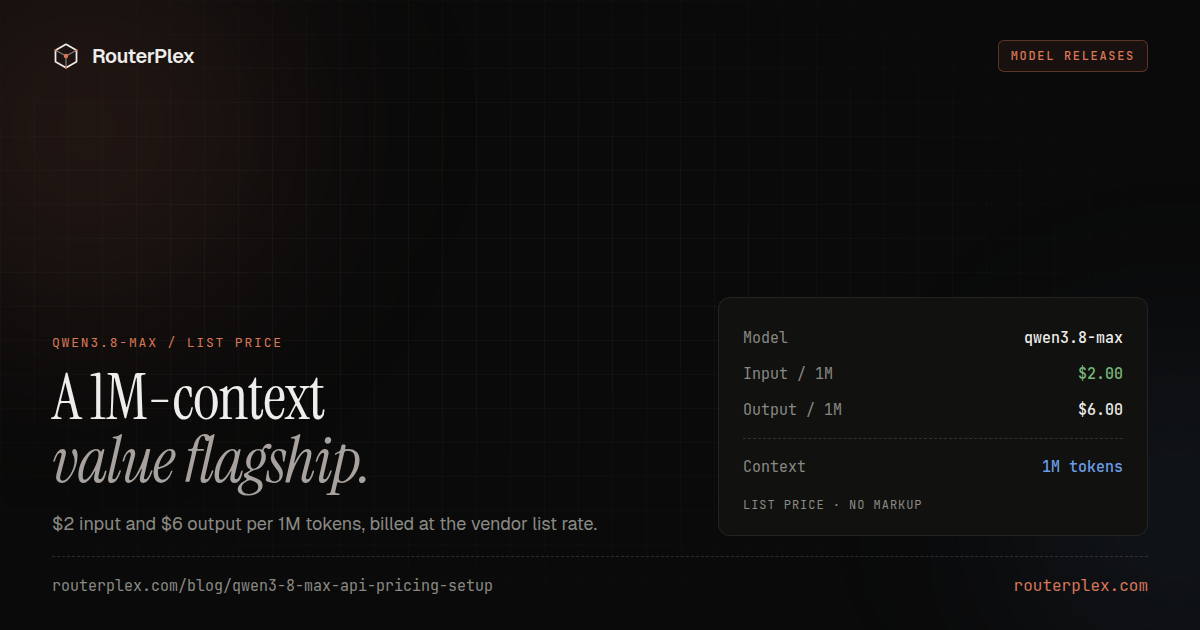
Alibaba does not publish a per-token rate for Qwen4-Max Preview. RouterPlex therefore bills it at the list price of Qwen3.8 Max, Alibaba's current flagship, so this rate is set by RouterPlex. Cached input (the part of a prompt the provider has seen before) bills at the full input rate on this model for now.
Reasoning tokens bill as output. A worked example: a 40,000-token prompt with a 2,000-token reply costs $0.092. That is $0.08 of input plus $0.012 of output. A $5 balance covers about 2.5 million input tokens.
How to call Qwen4-Max Preview
Set your key in the environment, then send a normal chat completion. Keep max_tokens large, because thinking counts against it (more on that below).
export ROUTERPLEX_API_KEY="your RouterPlex key"curl https://api.routerplex.com/v1/chat/completions \-H "Authorization: Bearer $ROUTERPLEX_API_KEY" \-H "Content-Type: application/json" \-d '{"model": "qwen4-max-preview","messages": [{"role": "user", "content": "Explain a hash map in two sentences."}],"max_tokens": 8000}'
The same ID works in the OpenAI Python SDK with base_url="https://api.routerplex.com/v1". It also works on the Anthropic Messages format at https://api.routerplex.com, so Claude Code can run it. Set ANTHROPIC_MODEL=qwen4-max-preview and follow the Claude Code docs.
Why Qwen4-Max Preview returns empty replies
Qwen4-Max thinks before it answers, and thinking is on by default. Alibaba changed one rule with this model. Starting with qwen4-max-preview, max_tokens caps thinking and the final answer together. Older Qwen models capped only the answer.
So a small limit can be used up by reasoning alone. AIHubMix reported that max_tokens: 300 came back with finish_reason: "length" and empty content. All 300 tokens went to reasoning.
Three fixes work:
- Raise
max_tokenswell above the answer you expect. 8,000 is a safe start for chat. - Send
"reasoning_effort": "low"for simple tasks (Alibaba's default isxhigh). In our test on 11 November, a two-sentence answer used 89 reasoning tokens by default and 7 withlow. - Treat
finish_reason: "length"with empty content as a failure in your code, and retry with a higher limit.
Token Plan vs per-token access
Alibaba sells Qwen4-Max Preview only through its Token Plan, a monthly credit bundle. Neurohive lists four personal tiers on 11 November 2026: Lite at $6 (20,000 credits), Essential at $10 (45,000), Standard at $18 (80,000) and Pro at $43 (200,000). New users pay $3 or $5 on the two smaller tiers until 30 November.
Alibaba does not say how many tokens a credit buys. The plan also limits use to interactive coding and agent tools. Scripts, backends, batch and scheduled jobs are not allowed, per Neurohive and Pasquale Pillitteri's write-up.
Per-token billing fits the other cases. You can call qwen4-max-preview from a script, a backend or a CI job. Each request shows its exact cost, and a hard budget on the key stops spending at the number you set. RouterPlex publishes this comparison and sells the prepaid balance described here.
Qwen4-Max Preview specs and status
| Spec | Value |
|---|---|
| Model ID on RouterPlex | qwen4-max-preview |
| Released | 11 November 2026 (preview) |
| Preview ends | 25 November 2026, 16:00 UTC |
| Context window | 1M tokens |
| Reasoning | On by default; Alibaba lists reasoning_effort low, medium or xhigh (default xhigh) |
| Tool calling | Yes |
| API formats on RouterPlex | OpenAI Chat Completions, Anthropic Messages |
Alibaba's plan page lists image understanding for the model. RouterPlex has not verified image input on this route, so send text for now. Alibaba has given no date for a full release. When the preview ends, change the ID to qwen3.8-max, which bills the same $2 / $6.
Qwen4-Max vs Qwen3.8 Max, Hy3 and Hy4
Live RouterPlex rates, USD per 1M tokens, checked 11 November 2026.
| Model ID | Input | Cached input | Output | Context |
|---|---|---|---|---|
qwen4-max-preview | $2.00 | $2.00 | $6.00 | 1M |
qwen3.8-max | $2.00 | $0.70 | $6.00 | 1M |
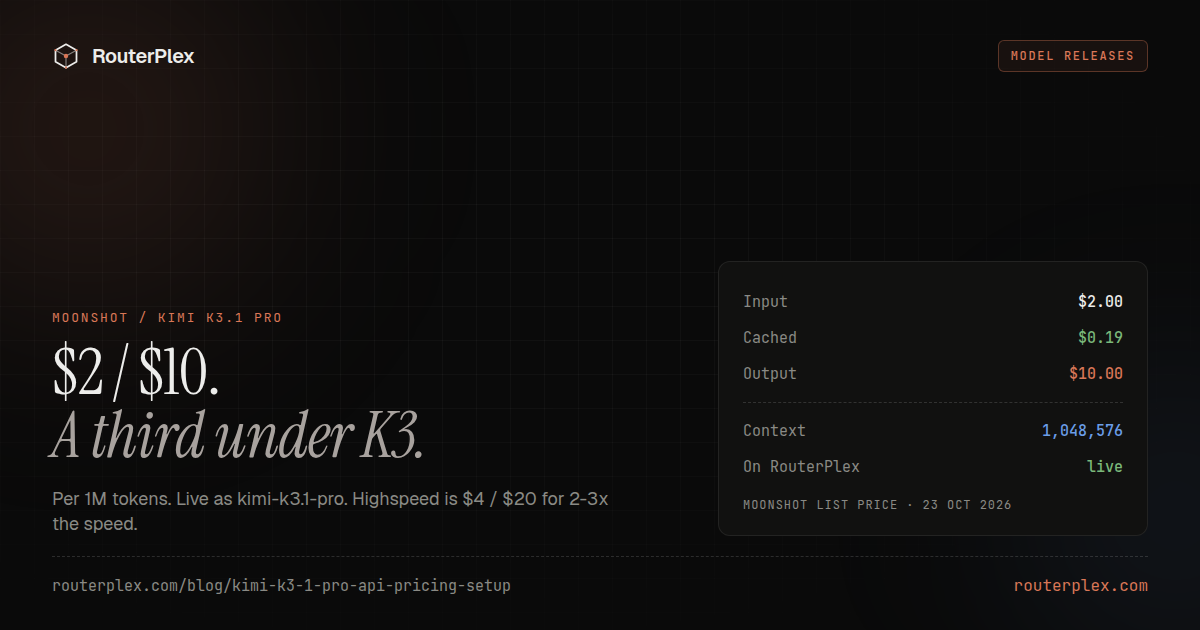
kimi-k3.1-pro | $2.00 | $0.19 | $10.00 | 1M |
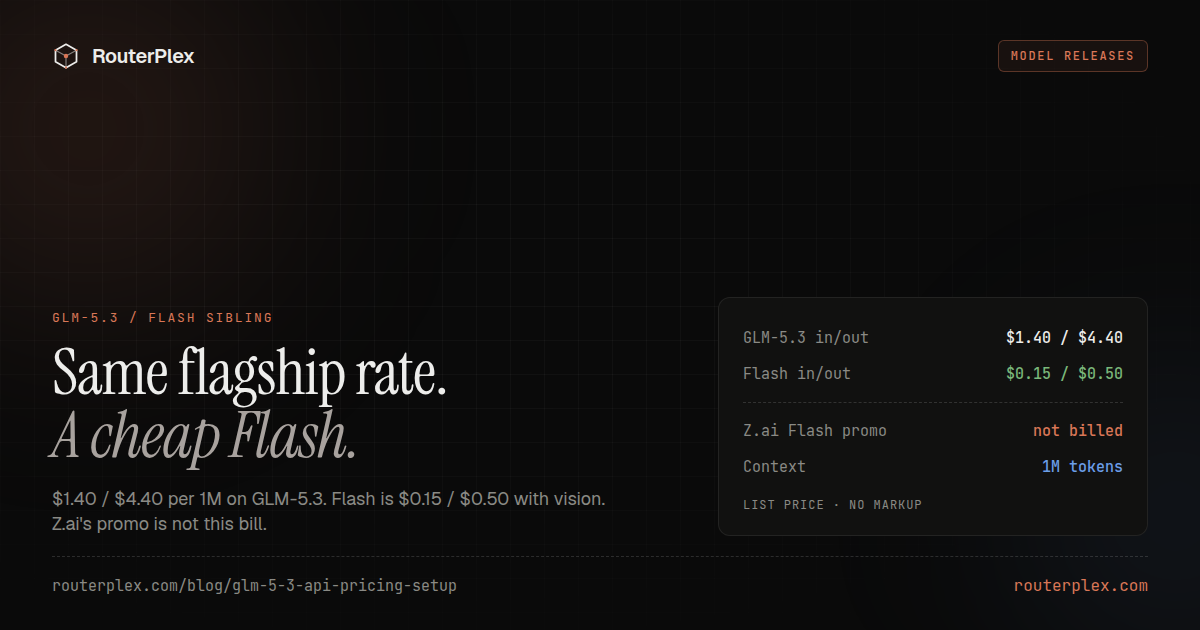
glm-5.3 | $1.40 | $0.26 | $4.40 | 1M |
deepseek-v4-pro | $0.80 | $0.21 | $2.39 | 1M |
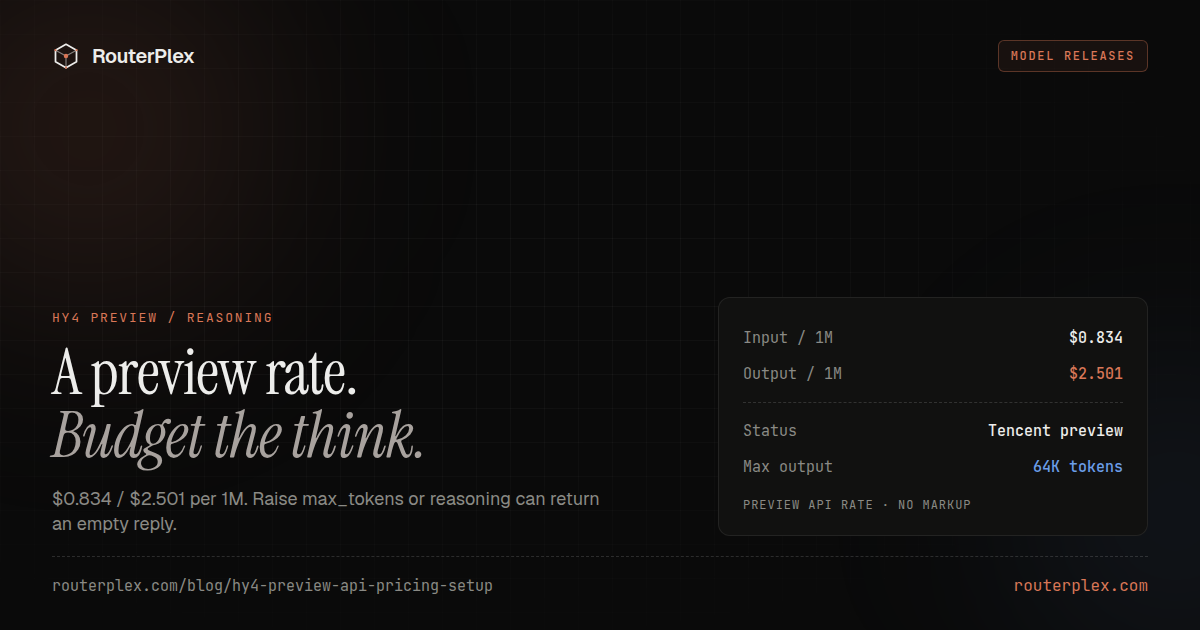
hy4-preview | $0.834 | $0.042 | $2.501 | 1M |
hy3 | $0.20 | $0.03 | $0.80 | 256K |
Qwen4-Max Preview and Qwen3.8 Max cost the same per fresh token. Qwen3.8 Max is cheaper on long agent sessions, because its cached input bills at $0.70.
Tencent's Hunyuan models sit at the low end. hy3 is back on RouterPlex as of 11 November and costs $0.20 / $0.80. The same 40K-in, 2K-out turn costs about $0.0096 on Hy3 and $0.038 on Hy4 Preview. For Hy4 rates and the Hy4 vs Preview difference, read the Hy4 API guide.
Common Qwen4-Max Preview errors
| What you see | Fix |
|---|---|
| 402 or "budget exceeded" | Your balance or key budget reached $0. RouterPlex stops at $0 and never bills a negative balance. Top up or raise the key budget. |
| 404 "model not found" | Use qwen4-max-preview, all lowercase. Alibaba's alias qwen4.0-max-preview is not a RouterPlex ID. |
Empty reply, finish_reason: "length" | Thinking used up max_tokens. Raise it or set reasoning_effort to low. |
| Errors after 25 November 2026 | The preview has ended. Switch to qwen3.8-max. |
Create a $5 RouterPlex account, set a hard budget on a key, and send one Qwen4-Max request today.
Common questions
Frequently asked questions
How much does the Qwen4-Max Preview API cost?
On RouterPlex, Qwen4-Max Preview costs $2 per 1M input tokens and $6 per 1M output tokens, checked 11 November 2026. Cached input bills at the $2 input rate for now, and reasoning tokens bill as output. Alibaba itself publishes no per-token price. It sells the model only inside its Token Plan subscription, priced in credits from $6 to $43 a month, and does not say how many tokens a credit buys. RouterPlex bills Qwen3.8 Max's list rate instead, so the rate is set by RouterPlex. A 40,000-token prompt with a 2,000-token reply costs about $0.092.
When does Qwen4-Max Preview end?
Alibaba's preview window closes at 24:00 Beijing time on 25 November 2026, which is 16:00 UTC that day, according to Neurohive and OrcaRouter on 11 November 2026. Alibaba says the preview model is retired after that. It has not published a date for a full Qwen4-Max release. On RouterPlex, plan to switch the model ID from qwen4-max-preview to qwen3.8-max when the preview ends. Qwen3.8 Max bills the same $2 input and $6 output per 1M tokens, so your budget math does not change.
Why does Qwen4-Max Preview return an empty response?
Starting with qwen4-max-preview, Alibaba counts thinking and the final answer against the same max_tokens limit. Reasoning is on by default, so a small limit can be spent before the model writes any answer. AIHubMix reported that max_tokens set to 300 returned finish_reason length with empty content, because all 300 tokens were reasoning. Raise max_tokens well above the answer size, for example 8,000 for chat. You can also send reasoning_effort set to low for simple tasks. In a RouterPlex test on 11 November 2026, that cut reasoning on a short answer from 89 tokens to 7.
Can I use Qwen4-Max Preview without a Token Plan subscription?
Yes. Alibaba itself offers the preview only through its Token Plan, and the plan limits use to interactive coding and agent tools, with scripts, backends and batch jobs not allowed, per Neurohive on 11 November 2026. RouterPlex serves the same model ID, qwen4-max-preview, per token from a prepaid balance. You can call it from scripts, servers and CI. There is no monthly fee and no top-up fee. Every API key can carry a hard spend budget, and the balance stops at $0 instead of going negative. RouterPlex wrote this answer and sells that prepaid balance.
Does Qwen4-Max Preview work in Claude Code?
Yes. RouterPlex serves qwen4-max-preview on the Anthropic Messages format as well as the OpenAI format. Set ANTHROPIC_BASE_URL to https://api.routerplex.com, ANTHROPIC_AUTH_TOKEN to your RouterPlex key, and ANTHROPIC_MODEL to qwen4-max-preview, then run claude. Thinking counts against the output limit on this model, so keep Claude Code's output limit high. Long coding sessions resend the same context each turn. Cached input bills at the full $2 rate on this model for now, so qwen3.8-max, with $0.70 cached input, costs less on long sessions.
Is Hy3 available on RouterPlex?
Yes. Tencent's Hy3 is live again on RouterPlex as of 11 November 2026, with model ID hy3. It costs $0.20 per 1M input tokens, $0.03 per 1M cached input tokens and $0.80 per 1M output tokens, with a 256K context window. Hy4 Preview is also live as hy4-preview at $0.834 input, $0.042 cached and $2.501 output per 1M tokens, with a 1M context window. Both are reasoning models, so leave room in max_tokens. For the Hy4 general release price and how Hy4 differs from the preview, see the RouterPlex Hy4 API guide.
Run the smallest paid test.
Add $5, cap the key, and verify the result with your own workload. No subscription, and credit never expires — a first top-up of $25+ is matched with $25 extra.