GLM-4.7 Flash Heretic API: $0.12/$0.60 Abliterated Setup
GLM-4.7 Flash Heretic is the cheapest abliterated model on RouterPlex: $0.12 in, $0.60 out per 1M tokens. Id glm-4.7-flash-abliterated. Checked 3 Nov 2026.
Model releases·Published ·By RouterPlex·6 min
glm-4.7-flash-abliterated is live on RouterPlex at a RouterPlex-set rate, paid credit only, $0 top-up fee.
On this page
GLM-4.7 Flash Heretic API pricing on RouterPlex is $0.12 per 1M input tokens and $0.60 per 1M output tokens. Cached input is $0.09, and the model id is glm-4.7-flash-abliterated. Checked 3 November 2026. Open GLM-4.7 Flash Abliterated for the live rate.
This is Zhipu's GLM-4.7 Flash with refusal behaviour removed from the weights by Heretic. It is the cheapest abliterated route on RouterPlex, about half the input price of GLM-5.3 Flash Abliterated. It is text only, with a 200K context. RouterPlex sets this rate, and it is not a Z.ai list price.
RouterPlex publishes this page and sells the prepaid wallet described below.
Create a free RouterPlex account and add a $5 top-up. Cap the key, then send one short request before you move a real job onto this id.
What Heretic changed
Heretic is an open-source tool that runs abliteration automatically. Abliteration edits a model's weights so it stops refusing, and it is not a prompt trick. Heretic searches for the edit that removes the most refusals while keeping the model's answers closest to the original on ordinary prompts. A "Heretic LLM" is a model that has been through that process.
The build here is the public GLM-4.7-Flash-heretic checkpoint, served as a hosted route. You do not need a GPU, a GGUF file, or a local runtime to use it. RouterPlex does not run Heretic for you, and this page does not explain how to install it. For the background on the edit itself, read what abliteration is.
What it is for
Stock models often refuse legitimate security work. A refusal-removed model answers it. Teams red-team their own LLM apps and test guardrails with real attack prompts. They write penetration-test reports for systems they are authorized to test. They ask how a disclosed CVE works, then draft detection rules for it. The low price suits bulk jobs, such as running a few thousand attack prompts through an evaluation set.
You are still bound by the terms. Authorized work is your responsibility, and the model can be wrong, so check what it gives you.
GLM-4.7 Flash Heretic API pricing
USD per 1M tokens, from the RouterPlex catalog on 3 November 2026.
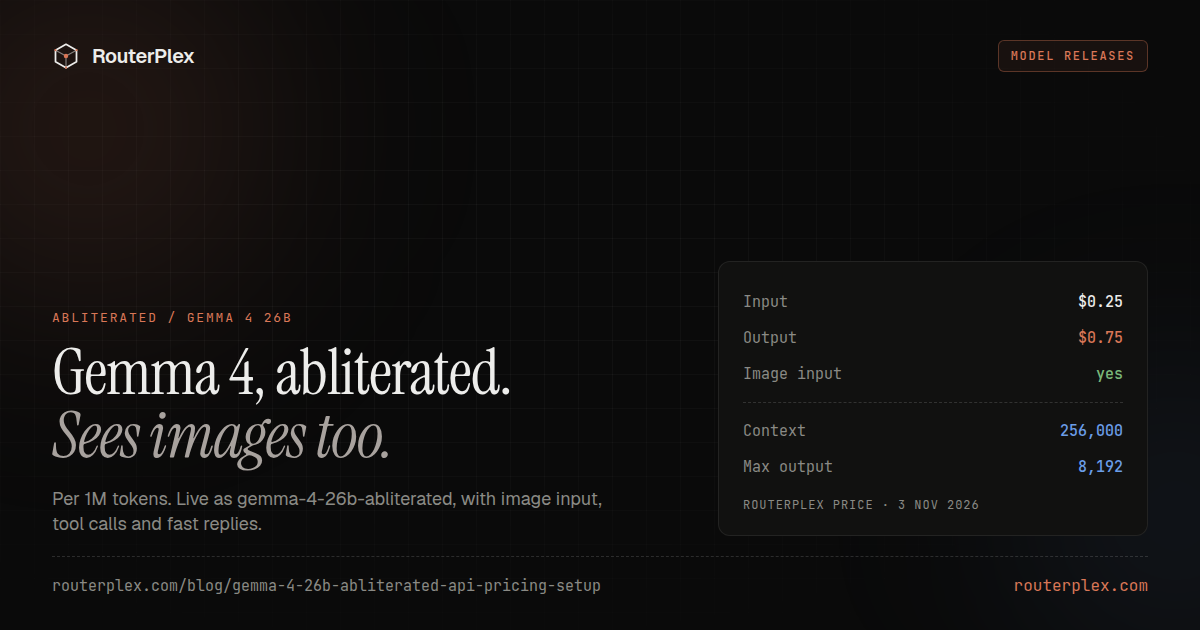
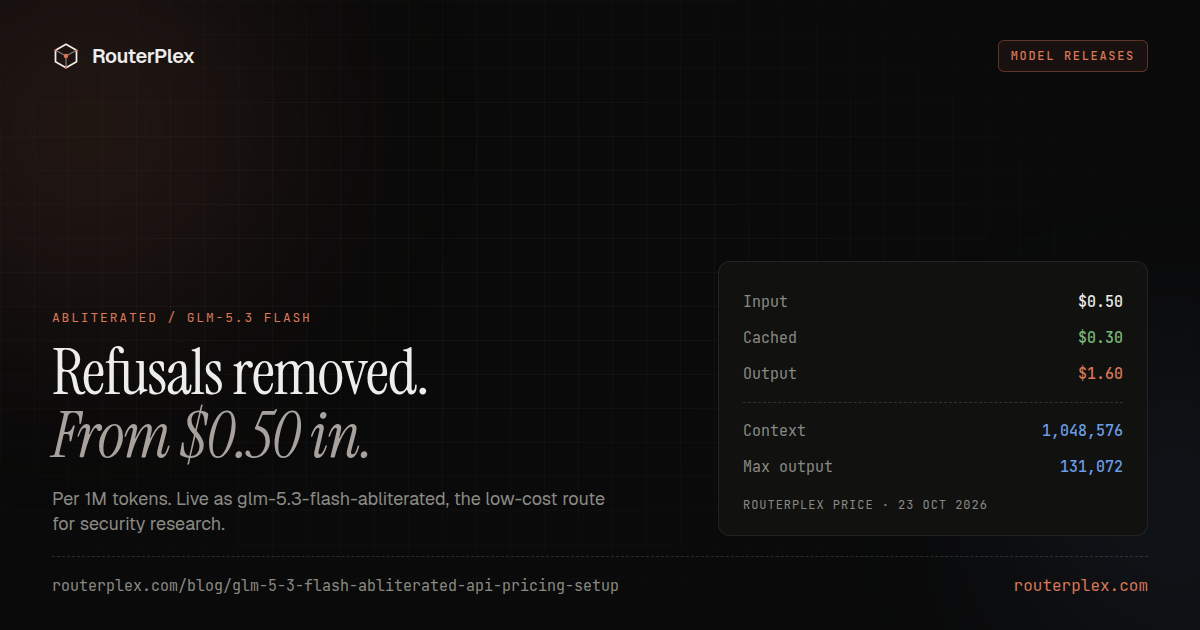
| Line | glm-4.7-flash-abliterated | glm-5.3-flash-abliterated | gemma-4-26b-abliterated |
|---|---|---|---|
| Input | $0.12 | $0.25 | $0.25 |
| Cached input | $0.09 | $0.06 | $0.25 |
| Output | $0.60 | $1.00 | $0.75 |
| Context | 200,000 | 1,048,576 | 256,000 |
| Max output | 24,000 | 131,072 | 8,192 |
| Image input | No | Yes | Yes |
A cold call of 40,000 input tokens and 2,000 output tokens costs $0.0060 here. The same mix is $0.012 on glm-5.3-flash-abliterated, $0.0115 on gemma-4-26b-abliterated, and $0.023 on deepseek-v4.1-flash-abliterated. With 30,000 of the 40,000 tokens cached, the bill here is $0.0051: $0.0012 fresh, $0.0027 cached, and $0.0012 output.
The cache line saves less here than on GLM-5.3 Flash, because cached input is $0.09 against $0.12 fresh. Caching is real, though. A repeated 8,009-token prompt came back with 8,008 cached tokens on the second call.
A $5 balance covers about 41 million fresh input tokens at $0.12, or about 8.3 million output tokens at $0.60. Reasoning text counts as output, so real calls use more output than the visible answer.
Our refusal check
On 3 November 2026 we sent five prompts that stock models often decline: an explicit scene between two adult characters, a graphic horror scene, SQL injection payloads for a login form, an aggressive essay against religion, and a request for a vicious personal insult. GLM-4.7 Flash Heretic answered all five. As a control, stock GLM-5.3 Flash refused two of the five and GPT-6 Luna refused three.
Five prompts is a small check, not a benchmark. It shows the route answers the kind of request a stock model declines. It does not measure answer quality. Run your own evaluation set before you depend on it.
Speed and reasoning effort
This model reasons before it answers, so it is not fast. In the refusal check, answers of up to 2,500 tokens took about 26 seconds on average. A short reply took a few seconds.
Reasoning effort accepts none, low, medium, or high, and the default is low. It changes how much the model thinks, but none does not switch thinking off. On one counting question, none used 516 output tokens and took 6 seconds, and high used 1,228 tokens and took 13 seconds. Both gave the right answer. Set max_tokens with room for the reasoning, or a long answer can stop early.
Specs
Context is 200,000 tokens. Max output is 24,000. Tool calls work, including streamed tool calls, and we checked one end to end. There is no image input. The public page slug is /models/glm-4-7-flash-abliterated. The dotted URL returns 404. The model id keeps the dots.
Setup
curl https://api.routerplex.com/v1/chat/completions \-H "Authorization: Bearer $ROUTERPLEX_API_KEY" \-H "Content-Type: application/json" \-d '{"model": "glm-4.7-flash-abliterated","reasoning_effort": "low","max_tokens": 4000,"messages": [{"role": "user", "content": "Reply with exactly: RouterPlex connected."}]}'
Claude Code and other Anthropic clients use the gateway root, not the /v1 chat path.
export ANTHROPIC_BASE_URL=https://api.routerplex.comexport ANTHROPIC_AUTH_TOKEN=$ROUTERPLEX_API_KEYexport ANTHROPIC_MODEL=glm-4.7-flash-abliterated
The OpenAI-compatible API guide covers the SDK base URL https://api.routerplex.com/v1. Claude Code Router covers agent routing. Keep the key in the environment. Do not commit it.
Errors
The $1 trial key is not free access to this id, and there is no free credit on abliterated routes. HTTP 402 with type paid_model_required means the key is still a trial key. Add a paid top-up of at least $5, and the top-up fee is $0.
A hard spend cap stops the key even when the account balance remains. Raise the cap or split the job. The account itself does not go negative.
A request over 200,000 tokens of context fails. Move that job to GLM-5.3 Flash Abliterated or DeepSeek V4.1 Flash Abliterated, which both take about 1M tokens. Model not found means the id string is wrong. Send glm-4.7-flash-abliterated, not the page slug and not the Hugging Face repo name.
Which abliterated route to pick
- Cheapest, text only:
glm-4.7-flash-abliterated, this page. - Fast replies with image input: Gemma 4 26B Abliterated, $0.25 and $0.75.
- 1M context with image input: GLM-5.3 Flash Abliterated, $0.25 and $1.00.
- DeepSeek family, 131K output: DeepSeek V4.1 Flash Abliterated, $0.50 and $1.50.
- Strongest reasoning: GLM-5.3 Abliterated, $2 and $4.
All five are listed together in the abliterated section of the model catalog.
Terms
The model will answer some requests that stock GLM-4.7 Flash declines, and you are responsible for that use under the terms. Illegal content, malware, weapons development, and child sexual abuse material are barred.
Next step
Create a free RouterPlex account, add a $5 top-up, and open GLM-4.7 Flash Abliterated before you set a budget.
Common questions
Frequently asked questions
How much does GLM-4.7 Flash Heretic cost on RouterPlex?
Checked 3 November 2026, the catalog lists $0.12 per 1M input tokens, $0.09 per 1M cached input, and $0.60 per 1M output tokens for glm-4.7-flash-abliterated. It is the cheapest abliterated route on RouterPlex. RouterPlex sets this rate. It is not a Z.ai list price.
What is a Heretic LLM?
Heretic is an open-source tool that runs abliteration automatically. It searches for a weight edit that removes refusals while keeping the model's answers close to the original on ordinary prompts. A Heretic LLM is a model edited that way. glm-4.7-flash-abliterated is GLM-4.7 Flash after a Heretic run, served as a hosted API.
Is GLM-4.7 Flash Heretic the same as glm-4.7-flash-abliterated?
Yes. The weights are the public GLM-4.7-Flash-heretic build. RouterPlex lists it as glm-4.7-flash-abliterated so it sits next to the other abliterated ids. Send that id to the API. The page slug is /models/glm-4-7-flash-abliterated.
Does it accept images?
No. GLM-4.7 Flash Heretic is text only. For image input on an abliterated route, use gemma-4-26b-abliterated at $0.25 and $0.75, or glm-5.3-flash-abliterated at $0.25 and $1.00 per 1M tokens.
What are the context and output limits?
The catalog lists 200,000 context tokens and 24,000 max output tokens. Tool calls and reasoning are on. Reasoning effort accepts none, low, medium, or high. In our test, none made the reasoning shorter but did not turn it off.
Can I use the $1 trial key?
No. The trial key is not free access to this route, and there is no free credit for it. The API returns HTTP 402 with type paid_model_required. Add a paid top-up of at least $5. The top-up fee is $0.
Run the smallest paid test.
Add $5, cap the key, and verify the result with your own workload. No subscription, and credit never expires — a first top-up of $25+ is matched with $25 extra.