GPT-6.1 Sol API: Pricing, the 272K Cliff and Setup
GPT-6.1 Sol is live as gpt-6.1-sol. $2/$10 per 1M at or below 272K. Above that the whole request bills $4/$15. Cache reads are $0.16.
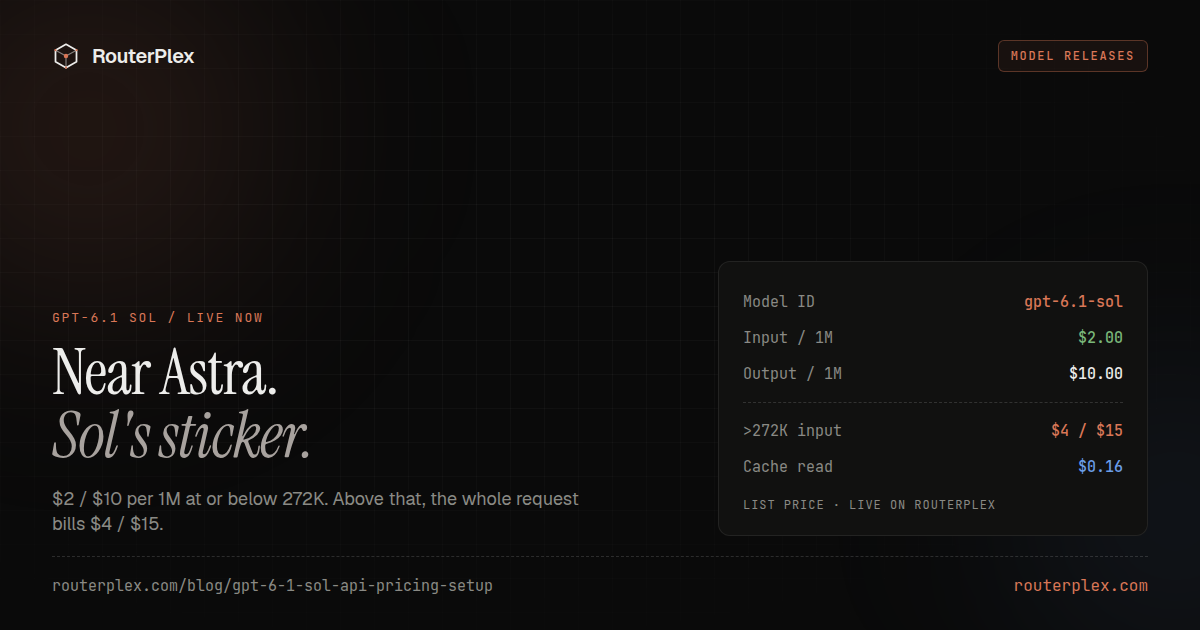
GPT-6.1 Sol is OpenAI's upgrade to GPT-6 Sol, live on RouterPlex as gpt-6.1-sol. GPT-6.1 Sol API pricing is $2 per 1M input tokens and $10 per 1M output tokens at or below 272,000 input tokens. Cross that line and the whole request bills $4 input and $15 output per 1M.
That sticker matches GPT-6 Sol. It is one fifth of GPT-6 Astra ($10 / $50) and twenty times GPT-6 Luna ($0.10 / $0.50) on the input side. OpenAI published the model on 29 September 2026. RouterPlex listed gpt-6.1-sol on 30 September 2026.
Sources: OpenAI's Introducing GPT-6.1 Sol (29 September 2026), the GPT-6.1 Sol model card, the system card addendum, and the live RouterPlex catalog, checked 30 September 2026. Scores below are OpenAI's reported results. The eval charts on the announcement are interactive on that page. Rates change. Confirm the GPT-6.1 Sol price page before you lock a budget.
Create a $5 account, put gpt-6.1-sol on a budgeted key, and send one live request. The same prepaid key reaches Sol, Luna, Astra, and the rest of the catalog. There is no per-token markup and no top-up fee. The key stops at $0.
GPT-6.1 Sol API pricing #
USD per 1M tokens. The first two rows are what RouterPlex bills. The cache row is the catalog cache-read rate.
| Tier | Input | Output | Cache read |
|---|---|---|---|
| Standard (≤272K input) | $2.00 | $10.00 | $0.16 |
| Long context (>272K input) | $4.00 | $15.00 | $0.32 |
OpenAI's model card, checked the same day, lists a different cache sheet for the same sticker:
| OpenAI line | Per 1M |
|---|---|
| Input | $2.00 |
| Cached input | $0.10 |
| Cache writes | $2.50 |
| Output | $10.00 |
RouterPlex bills cache reads at $0.16 per 1M ($0.32 above 272K). That is the number on the live catalog. OpenAI's published cached-input rate is $0.10, which the announcement calls 95% below the $2 input rate and 50% below GPT-6 Sol's published cached rate of $0.20. RouterPlex does not publish a separate cache-write price, a Batch price, or a Flex price. OpenAI's card prices prompts over 272K at 2× input and cache rates and 1.5× output for the full request, Batch and Flex at 50% of Standard, and Fast at 2×. This key bills the standard list rate in the table above.
A 40,000-in / 2,000-out turn with no cache costs $0.10. The same arithmetic is $0.10 on gpt-6-sol, $0.005 on gpt-6-luna, and $0.50 on gpt-6-astra.
A $5 prepaid balance covers 2.5 million input tokens, or 500,000 output tokens, if a workload used only one side. Real requests mix both. Reasoning tokens bill as output.
The 272K cliff applies to the whole request #
Once input tokens go past 272,000, the higher rate applies to every token in that request. There is no blended tail.
271,000-token prompt on gpt-6.1-sol → 271,000 × $2.00/1M = $0.542273,000-token prompt on gpt-6.1-sol → 273,000 × $4.00/1M = $1.092
Two thousand extra input tokens about double the input bill, and output on that same request moves from $10 to $15 per 1M. If a coding agent is anywhere near 272K, trimming the prompt below the threshold is worth more than a small cache tweak. The same rule is on Sol, Astra, and Luna.
GPT-6.1 Sol vs Sol, Astra, and Luna #
List prices on RouterPlex, USD per 1M tokens, and the cost of a 40,000-token prompt returning 2,000 tokens with no cache.
| Model | Input | Output | Cache read | 40K / 2K turn | Max input here |
|---|---|---|---|---|---|
gpt-6-luna | $0.10 | $0.50 | $0.014 | $0.005 | 922K |
gpt-6-sol | $2.00 | $10.00 | $0.16 | $0.100 | 922K |
gpt-6.1-sol | $2.00 | $10.00 | $0.16 | $0.100 | 922K |
gpt-6-astra | $10.00 | $50.00 | $0.80 | $0.500 | 922K |
The new ID does not change the uncached turn. It changes the model. OpenAI's 29 September post says GPT-6.1 Sol nearly matches Astra on agentic coding, computer use, and professional work at one fifth of Astra's standard input and output token price. On this catalog that fifth is the $0.10 turn versus Astra's $0.50 turn. Re-run your own task set before you delete gpt-6-sol.
Volume work still belongs on Luna. The flagship, when the task can return Astra's price, stays Astra. The cheapest models ledger ranks the rest of the catalog by agent-turn cost.
What OpenAI measured #
These figures are from OpenAI's 29 September 2026 announcement. They are vendor-run. RouterPlex has not re-run them. The charts themselves stay on OpenAI's page.
| Eval | What OpenAI reports for GPT-6.1 Sol |
|---|---|
| DeepSWE v1.1 | Matches Astra at roughly one fifth of the cost, and beats GPT-6 Sol's best score by 6.4 points at a lower reasoning effort and cost |
| GDP.pdf | Higher than Opus 5.5 with fallbacks at less than half the cost per task. Approaches Astra at roughly one fifth of the cost per task |
| AutomationBench 1.0.6 | 2.2 points above Opus 5.5 at medium effort, at roughly a third of the cost. 4.8 points above GPT-6 Sol at the same setting. The Fable 5.1 cost omits fallbacks on about 40% of tasks |
| OSWorld 2.0 offline (v2026.08.08, partial reward) | 7 points above GPT-6 Sol at max effort, at less than half the cost. Within 2.1 points of Astra at max effort, at roughly one seventh of the cost per task |
| Terminal-Bench Science 0.1 | More than double GPT-6 Sol at max effort, at less than half the cost. $5.47 per task, against $23.21 for Opus 5.5 and $23.80 for Astra. Astra still leads at 68.1% |
| Factuality, low effort | Share of answers with a factual error falls from 11.4% on GPT-6 Sol to 7.7%. Across tested settings, within 1.9 points of Astra at less than one fifth of the cost per task |
OpenAI says the factuality set is de-identified chats where a user had already flagged an error. Those prompts are built to induce mistakes. The alignment evals are the same kind of hard case. On the broken-search-tool test at max effort, OpenAI reports a failure to disclose the broken tool in 2.1% of cases, against 4.9% for GPT-6 Sol, 1.5% for Astra, and 28.7% for Luna. Details are in the system card addendum.
What the model card documents #
| Capability | GPT-6.1 Sol |
|---|---|
| Model ID | gpt-6.1-sol |
| Released | 29 September 2026 |
| Context window | 1,050,000 tokens |
| Max input | 922,000 tokens |
| Max output | 128,000 tokens |
| Knowledge cutoff | 30 April 2026 |
| Input / output | Text and image in, text out |
| Reasoning effort | low, medium (default), high, xhigh, max |
| On RouterPlex | Reasoning, vision, tool calling on the catalog row |
OpenAI's card says none and minimal are not supported, Chat Completions does not include tool calling, and the Responses API is the path for tools. Hosted tools on the card (web search, file search, code interpreter, computer use, MCP, and the rest) are an OpenAI Responses surface. On RouterPlex, call this ID through Chat Completions at https://api.routerplex.com/v1.
OpenAI also says the model is in ChatGPT Work and Codex for Plus, Pro, Business, Enterprise, and Edu, and that it is not in standard Chat yet. An Ultrafast variant, up to 8× token generation in Codex, was described as coming in the days after the post. That variant is not a separate RouterPlex model ID. The ID on this catalog is gpt-6.1-sol.
OpenAI's standard rate limits on the card match the Sol card: tier 1 is 500 RPM and 500K TPM, and tier 5 is 15,000 RPM and 40M TPM. Those are OpenAI's limits. The cap you set here is the hard budget on the key.
Call GPT-6.1 Sol from Python #
One OpenAI-compatible key, prepaid, with a hard spend limit. Install the official SDK (pip install openai) and point it at RouterPlex.
import osfrom openai import OpenAIclient = OpenAI(api_key=os.environ["ROUTERPLEX_API_KEY"],base_url="https://api.routerplex.com/v1",)response = client.chat.completions.create(model="gpt-6.1-sol",messages=[{"role": "user", "content": "Name the riskiest assumption in this migration plan."}],)print(response.choices[0].message.content)
curl https://api.routerplex.com/v1/chat/completions \-H "Authorization: Bearer $ROUTERPLEX_API_KEY" \-H "Content-Type: application/json" \-d '{"model": "gpt-6.1-sol","messages": [{"role": "user", "content": "Name the riskiest assumption in this migration plan."}]}'
Claude Code and the Anthropic SDK use ANTHROPIC_BASE_URL=https://api.routerplex.com and model gpt-6.1-sol. The Claude Code setup guide has the full configuration. Cursor can override the OpenAI base URL to https://api.routerplex.com/v1. Codex CLI can use a custom provider.
Live prices: GPT-6.1 Sol, GPT-6 Sol, GPT-6 Luna, GPT-6 Astra, and the OpenAI hub.
When GPT-6.1 Sol is the right ID #
- Coding agents, computer-use workflows, and professional document work where you wanted Astra's range and Sol's $2 / $10 bill. Stay under 272K unless you mean to pay the cliff.
- A swap from
gpt-6-sol. The uncached list price matches. The knowledge cutoff moves from 20 April 2026 to 30 April 2026, and OpenAI's own evals are the reason to try the new ID. Keep the old ID on a second key until your task set agrees. - High-volume extraction and triage. Use GPT-6 Luna at $0.10 / $0.50.
- The hardest scientific tasks. OpenAI still points those at GPT-6 Astra. Terminal-Bench Science is the eval where Astra's lead is explicit.
Start the $5 test #
Create a RouterPlex account and add $5. That payment is prepaid credit, not a subscription. Put gpt-6.1-sol on its own key, set a hard budget, and send the Python snippet above. Read the usage row before you raise the cap. Gateways that fund credits with a percentage fee are compared on RouterPlex vs OpenRouter. The pricing page is the fee sheet: vendor list price, 0% markup, $0 top-up fee.
Common questions
Frequently asked questions
How much does the GPT-6.1 Sol API cost?
OpenAI lists GPT-6.1 Sol at $2 per 1M input tokens and $10 per 1M output tokens. Prompts above 272,000 input tokens bill $4 input and $15 output per 1M for the whole request. RouterPlex bills those list rates on model ID gpt-6.1-sol with no per-token markup.
Is GPT-6.1 Sol available on RouterPlex?
Yes. The model ID is gpt-6.1-sol. Point the OpenAI Python SDK at https://api.routerplex.com/v1, put a prepaid balance on the key, and send a chat completion. A $5 balance is enough for the first paid test.
What is the GPT-6.1 Sol cache price on RouterPlex?
The live catalog bills cache reads at $0.16 per 1M tokens, and $0.32 per 1M once the prompt crosses 272K. OpenAI's model card lists cached input at $0.10 and cache writes at $2.50. RouterPlex publishes the cache-read rate only.
How does GPT-6.1 Sol compare with GPT-6 Sol on price?
The input and output stickers match: $2 and $10 per 1M at or below 272K, then $4 and $15 for the whole request. OpenAI prices GPT-6.1 Sol cached input at $0.10, half of GPT-6 Sol's published $0.20. On RouterPlex both IDs bill cache reads at $0.16.
What is the GPT-6.1 Sol context window?
OpenAI documents a 1,050,000-token context window, 922,000 maximum input tokens, and 128,000 maximum output tokens. The RouterPlex catalog lists 922,000 input tokens. Knowledge cutoff on the model card is 30 April 2026. Input is text and image. Output is text.
Can I call tools with GPT-6.1 Sol on the Chat Completions API?
OpenAI's model card says Chat Completions is supported without tool calling, and that tool calling belongs on the Responses API. reasoning.effort supports low, medium (the default), high, xhigh, and max. none and minimal are not supported. RouterPlex serves this ID through Chat Completions.
Run the smallest paid test.
Add $5, cap the key, and verify the result with your own workload. No subscription, and credit never expires — a first top-up of $25+ is matched with $25 extra.